Librosa Python Tutorial: Introduction to Audio Signal Processing
Librosa is a Python library for music and audio analysis that loads audio files, extracts spectral features (MFCC, mel-spectrogram, chroma, spectral contrast), and applies effects such as pitch shifting and time stretching. Librosa’s first release on PyPI was on 14 December 2013 (version 0.2.0); the library and its design were later described in an academic paper presented at the SciPy 2015 conference. This post is a practical, code-first Python Librosa tutorial covering audio feature extraction for machine learning workflows.
Are you ready to dive into audio processing with Python? A colleague recently sparked my interest in music-retrieval applications, and that sent me down the Librosa rabbit hole. This post is an introduction to Python’s Librosa library for extracting wave features commonly used in research and application tasks such as gender prediction, music genre prediction, and voice identification. Before tackling these complex tasks, though, we need to understand the basics of signal processing and how they relate to working with WAV files — so let’s start there.
How Digital Audio Signals Are Stored and Processed
What is an audio signal?
An audio signal is a representation of sound waves in the air. These sound waves are captured by a microphone and converted into an electrical signal, which can then be stored and manipulated digitally.
To store an audio signal digitally, the analogue electrical signal is first sampled at regular intervals, typically at 44,100 samples per second for CD-quality audio. Each sample is represented as a binary number with a certain bit depth, such as 16 bits. The higher the bit depth, the more accurately the analogue signal’s amplitude can be represented.
The binary numbers are then stored in a digital audio file format like WAV or MP3. The audio signal is typically compressed in these formats to reduce file size while maintaining acceptable audio quality. This compression can be lossless, meaning that no audio data is lost, or lossy, meaning that some audio data is discarded.
When the digital audio file is played back, the binary numbers are converted back into an analogue electrical signal by a digital-to-analogue converter, which can then be amplified and played through a speaker or headphones to produce sound waves in the air.
Audio can be stored in files using different formats, depending on the application and the user’s requirements. Some of the most common formats used for storing audio in files include:
- MP3: This compressed audio format is widely used for music playback and streaming. It offers high-quality audio with relatively small file sizes, making it a popular choice for storing and sharing music files.
- WAV: This uncompressed audio format provides high-quality audio with no loss of fidelity. It is commonly used for recording and editing audio files, as well as for creating audio CDs.
- AAC: This compressed audio format is similar to MP3 but offers better sound quality at lower bitrates. It is commonly used for streaming audio and video content.
- FLAC: This lossless compressed audio format provides high-quality audio with no loss of fidelity. It is commonly used for storing and sharing high-resolution audio files.
- OGG: This compressed audio format is commonly used for streaming audio and video content, and it offers high-quality audio with relatively small file sizes.
- AIFF: This uncompressed audio format provides high-quality audio with no loss of fidelity. It is commonly used for recording and editing audio files on Apple computers.
The choice of format depends on factors such as the audio quality, the file size, and the compatibility with the playback device or software.
Python libraries for audio processing
There are several Python libraries for audio processing, each with its features and capabilities. Here are some of the most popular and widely used libraries for audio processing in Python:
- NumPy is a fundamental library in Python for numerical computing. It provides the ability to perform various numerical operations on arrays, such as filtering, resampling, and FFT (Fast Fourier Transform).
- SciPy is built on top of NumPy and provides additional scientific and technical computing functionalities, including digital signal processing (DSP), Fourier analysis, and filter design.
- Librosa is a library for analysing and processing audio signals. It includes functionality for feature extraction, beat tracking, pitch estimation, and more.
- Pydub is a simple and easy-to-use library for working with audio files in Python. It allows you to load, manipulate, and save various audio file formats, including MP3, WAV, and AIFF.
- Soundfile is a library for reading and writing sound files. It supports various file formats, such as WAV, FLAC, and OGG, and provides a simple and straightforward interface for working with audio data.
- PyAudio provides a Python interface to the PortAudio library, a cross-platform library for audio input and output. It allows you to record and playback audio in real-time and supports various input and output devices.
- FFMpeg: FFMpeg is a command-line tool for manipulating video and audio files. Several Python bindings for FFMpeg, including moviepy and ffmpeg-python, provide a simple and easy-to-use interface for working with FFMpeg from Python.
Which library is best depends on your specific use case and project requirements.
In this post, I focus on using Librosa, providing a great starting point for audio processing in Python. I will also use wave, sounddevice, soundfile and, of course, NumPy!
Installing Librosa and Audio Processing Libraries in Python
First, you’ll need to install a few libraries to work with audio files in Python. Besides librosa, there are a few useful libraries for audio processing, such as NumPy and SciPy (check the scipy.signal). You can install them using pip. We can also use the sounddevice library 4 to play our sound, soundfile to save our audio files.
Additionally, we can use the wave module from the Python standard library, which provides an interface to work with WAV files.
pip install librosa
pip install numpy
pip install soundfile
pip install sounddevice
As usual, importing the required libraries beforehand we start coding.
import librosa
import numpy as np
import soundfile as sf
import wave
import sounddevice as sd
Working with WAV Files in Python
WAV for audio storage
WAV files have the extension .wav and can be played on most media players, including Windows Media Player, iTunes, and VLC Media Player. WAV is a standard file format for storing high-quality audio and is supported by many devices and audio applications. WAV files are uncompressed, keeping the raw audio data without losing quality. This results in large file sizes but ensures the audio quality is preserved.
WAV files are often used in professional audio applications such as recording studios and sound production, where high-quality audio is required. The WAV format is flexible and supports various audio formats, including mono and stereo, 8-bit and 16-bit, and different sample rates. This makes WAV files popular for audio storage, especially for high-quality audio applications.
Recording voice
Here’s an example of recording voice using the sounddevice library and saving it as a WAV file with wave. You can also use pyaudio, another popular library for recording and playing audio.
import sounddevice as sd

# Set the sampling frequency and duration of the recording
sampling_frequency = 44100
duration = 5  # in seconds

# Record audio
print("Recording...")
audio = sd.rec(int(sampling_frequency * duration), samplerate=sampling_frequency, channels=1)
sd.wait()  # Wait until recording is finished
print("Finished recording")
The sample rate is the number of samples or times the audio signal is measured per second.
The sample rate determines the precision and accuracy of the audio signal representation. A higher sample rate means the audio signal is sampled more frequently, resulting in a more detailed and accurate representation. On the other hand, a lower sample rate leads to a lower precision and accuracy representation of the audio signal.
Standard sample rates include 44.1 kHz, 48 kHz, and 96 kHz. The most commonly used sample rate for music is 44.1 kHz, used in CDs and considered a standard for high-quality audio.
Changing the sample rate affects the sound: a higher sample rate gives you higher quality and a larger file, a lower one gives you the opposite.
Saving an audio file
To save our recording, we can use the soundfile’s write function as follows.
import soundfile as sf

# Save the recorded audio to a WAV file
sf.write('voice.wav', audio, sampling_frequency)
This code will record 5 seconds of audio using the default microphone, save it as a WAV file with a sample rate of 44.1 kHz and 16-bit depth, and print the name of the saved file to the console. You can adjust the duration variable to change the length of the recording and the file_name variable to change the name of the saved file.
Playing an audio file
To play an audio in Python, we can use the sounddevice library:
sd.play(audio, fs)
sd.wait()
In this example, we use the play() function to play the signal array at the specified framerate, and then we use wait() to wait until the sound is finished playing.
Loading WAV files
To load a WAV file, we can use the “wave” module:
with wave.open('voice.wav', 'rb') as wav_file:
    channels_number, sample_width, framerate, frames_number, compression_type, compression_name = wav_file.getparams()
    frames = wav_file.readframes(frames_number)
    audio_signal = np.frombuffer(frames, dtype='<i2')
channels_number, sample_width, framerate, frames_number, compression_type, compression_name
(1, 2, 44100, 220500, 'NONE', 'not compressed')
In this example, we open the audio.wav file in read-only mode (‘rb’), and then we extract some metadata from the file using the getparams() method. We then read all the audio frames into a bytes object and convert them to a NumPy array with the frombuffer() method, specifying the data type as <i2 (16-bit signed integers).
If you prefer using Jupyter notebooks or Google Colab, you can also play the audio files using the Audio function in the IPython.display.
from IPython.display import Audio

Audio(audio_signal, rate=sampling_frequency)
Librosa Use Cases: Loading and Analysing Audio Files
Librosa is a Python library for analysing audio signals and provides functions for loading, transforming, and manipulating audio signals. The library has a simple, easy-to-use interface and supports various audio file formats, such as .wav and .mp3.
Beforehand, we can download some sound files to be loaded and analysed with librosa.
There are plenty of sound file resources online. In my further tests, I use the soundtracks recorded by LoopMaiden and available in the following resources.
- Sacrifice (mp3) https://freesound.org/people/LoopMaiden/sounds/567852/
- Drums (mp3) https://freesound.org/people/LoopMaiden/sounds/565186/
I use wget to download the sound files locally when working in Jupyter notebooks.
# Getting the sacrifice sound file
!wget https://cdn.freesound.org/previews/567/567852_12708796-lq.mp3

# Getting the drums' sound file
!wget https://cdn.freesound.org/previews/565/565186_12708796-lq.mp3
Next, we use the sacrifice_file and drums_file variable names for storing the corresponding file names.
# Keep the file names for further use
sacrifice_file = "567852_12708796-lq.mp3"
drums_file = "565186_12708796-lq.mp3.1"
Loading an Audio File with librosa.load()
To load an audio file using Librosa, you can use the librosa.load function. This function takes the file path as an argument and returns the audio signal and sample rate.
# load the audio signal and its sample rate
sacrifice_signal, sample_rate = librosa.load(sacrifice_file)
The sacrifice_file is pointing to an MP3 file. To load an MP3 file with librosa, you can simply use the librosa.load() function and specify the path to the MP3 file.
This is so easy because librosa.load() decodes through soundfile, which handles WAV, FLAC, OGG, AIFF, and — on current libsndfile builds — MP3 natively. Update: back when I first wrote this post, soundfile fell back to the audioread library for formats it couldn’t read, such as older MP3 files, and that fallback needed a system FFmpeg build. That fallback is gone now: audioread support was deprecated in librosa 0.10.0 and fully removed in librosa 1.0.0 (released August 2026). I re-tested this exact MP3 (sacrifice_file) against current librosa, and a plain librosa.load() call loads it fine, no FFmpeg required.
Fixing MP3-loading errors with Librosa
If you’re on an older librosa (before 1.0, without a recent libsndfile), librosa.load() can raise librosa.util.exceptions.NoBackendError when the audioread backend can’t find a decoder for the audio file, most often an MP3. The cause is a missing system FFmpeg build, which audioread relies on for compressed formats. Fix it by installing FFmpeg:
# macOS (Homebrew)
brew install ffmpeg
# Debian / Ubuntu
sudo apt-get install ffmpeg
Update: on librosa 1.0.0 and later, audioread — and NoBackendError with it — has been removed from the library entirely, so this fix no longer applies there; MP3s decode through soundfile’s libsndfile backend by default. If librosa.load() still fails on an MP3 on a current install, you’ll see a soundfile error instead (e.g. a LibsndfileError), which usually means the file itself is corrupt or uses a codec libsndfile doesn’t support — installing FFmpeg won’t fix that case.
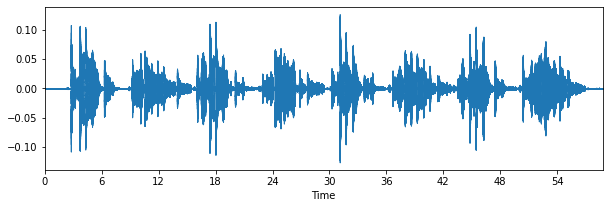
Plotting the signal
With the librosa.display, we can display the signal amplitude of the song in time.
import librosa.display
import matplotlib.pyplot as plt

plt.figure(figsize=(10, 3))
librosa.display.waveshow(sacrifice_signal, sr=sample_rate)
plt.show()
If you’re following an older tutorial and see librosa.display.waveplot() instead, skip it — that function was removed in librosa 0.9.0 in favour of waveshow().
Final thoughts
🔒 Subscribe to keep reading.
Soundtracks
🔒 Subscribe to keep reading.
References
🔒 Subscribe to keep reading.