Running DeepSeek R1 Locally with Ollama: Overview
Ollama is an open-source runtime that downloads and runs large language models locally from a single command line, and DeepSeek R1 is an open-source reasoning model whose distilled variants match OpenAI-o1-class performance. Large Language Models (LLMs) are becoming more popular, especially as people want to run AI tools on their devices. Running a model locally protects your privacy, reduces wait times, and lowers costs.
Two tools making this possible are:
- Ollama: A command-line tool to run Llama-based models locally.
- DeepSeek R1: An open-source reasoning language model from the Chinese company DeepSeek that’s gaining attention quickly.
What is DeepSeek R1, and is it better than ChatGPT and other AI models?
According to a TechCrunch article by Maxwell Zeff, DeepSeek has surpassed popular AI models like ChatGPT in downloads and usage, thanks to its open models that compete at a lower cost. The app has seen over 300% more downloads than Perplexity in just a week [1]!
So the open source models of DeepSeek become very interesting to investigate and try out for me, as a notorious GPT user :)
This post will explore how to use Ollama and DeepSeek R1 together. We’ll walk through their installation and basic usage.
I will surely use Ollama to download and run the DeepSeek R1 model and briefly compare it with the Llama3.2 model.
What Is Ollama?
Ollama is an open-source app that allows you to run large language models like Llama on your own machine.
It provides:
- Local Inference: Your data stays on your machine when you run the model.
- Command-Line Interface: Easily interact with the model directly from your terminal.
- Easy Model Management: Simple downloads and updates for different language models.
Ollama aims to make experimenting with LLMs easy without needing cloud services.
Installing Ollama
To install Ollama:
- Visit the Download Ollama page or the Ollama GitHub.
- Download the latest installer for your platform.
- Open the installer and follow the on-screen instructions.
You can check if Ollama is installed successfully by running the command:
It should display Ollama’s version:
Using Homebrew
If you prefer using Homebrew, ensure you have it installed.
You can use the following command to install Homebrew with curl:
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
Then, install Ollama with this command:
Update: Homebrew used to require the ollama/tap/ollama tap; Ollama now ships as a core Homebrew formula, so a plain brew install ollama is all you need. Once the installation completes, verify:
Ollama models
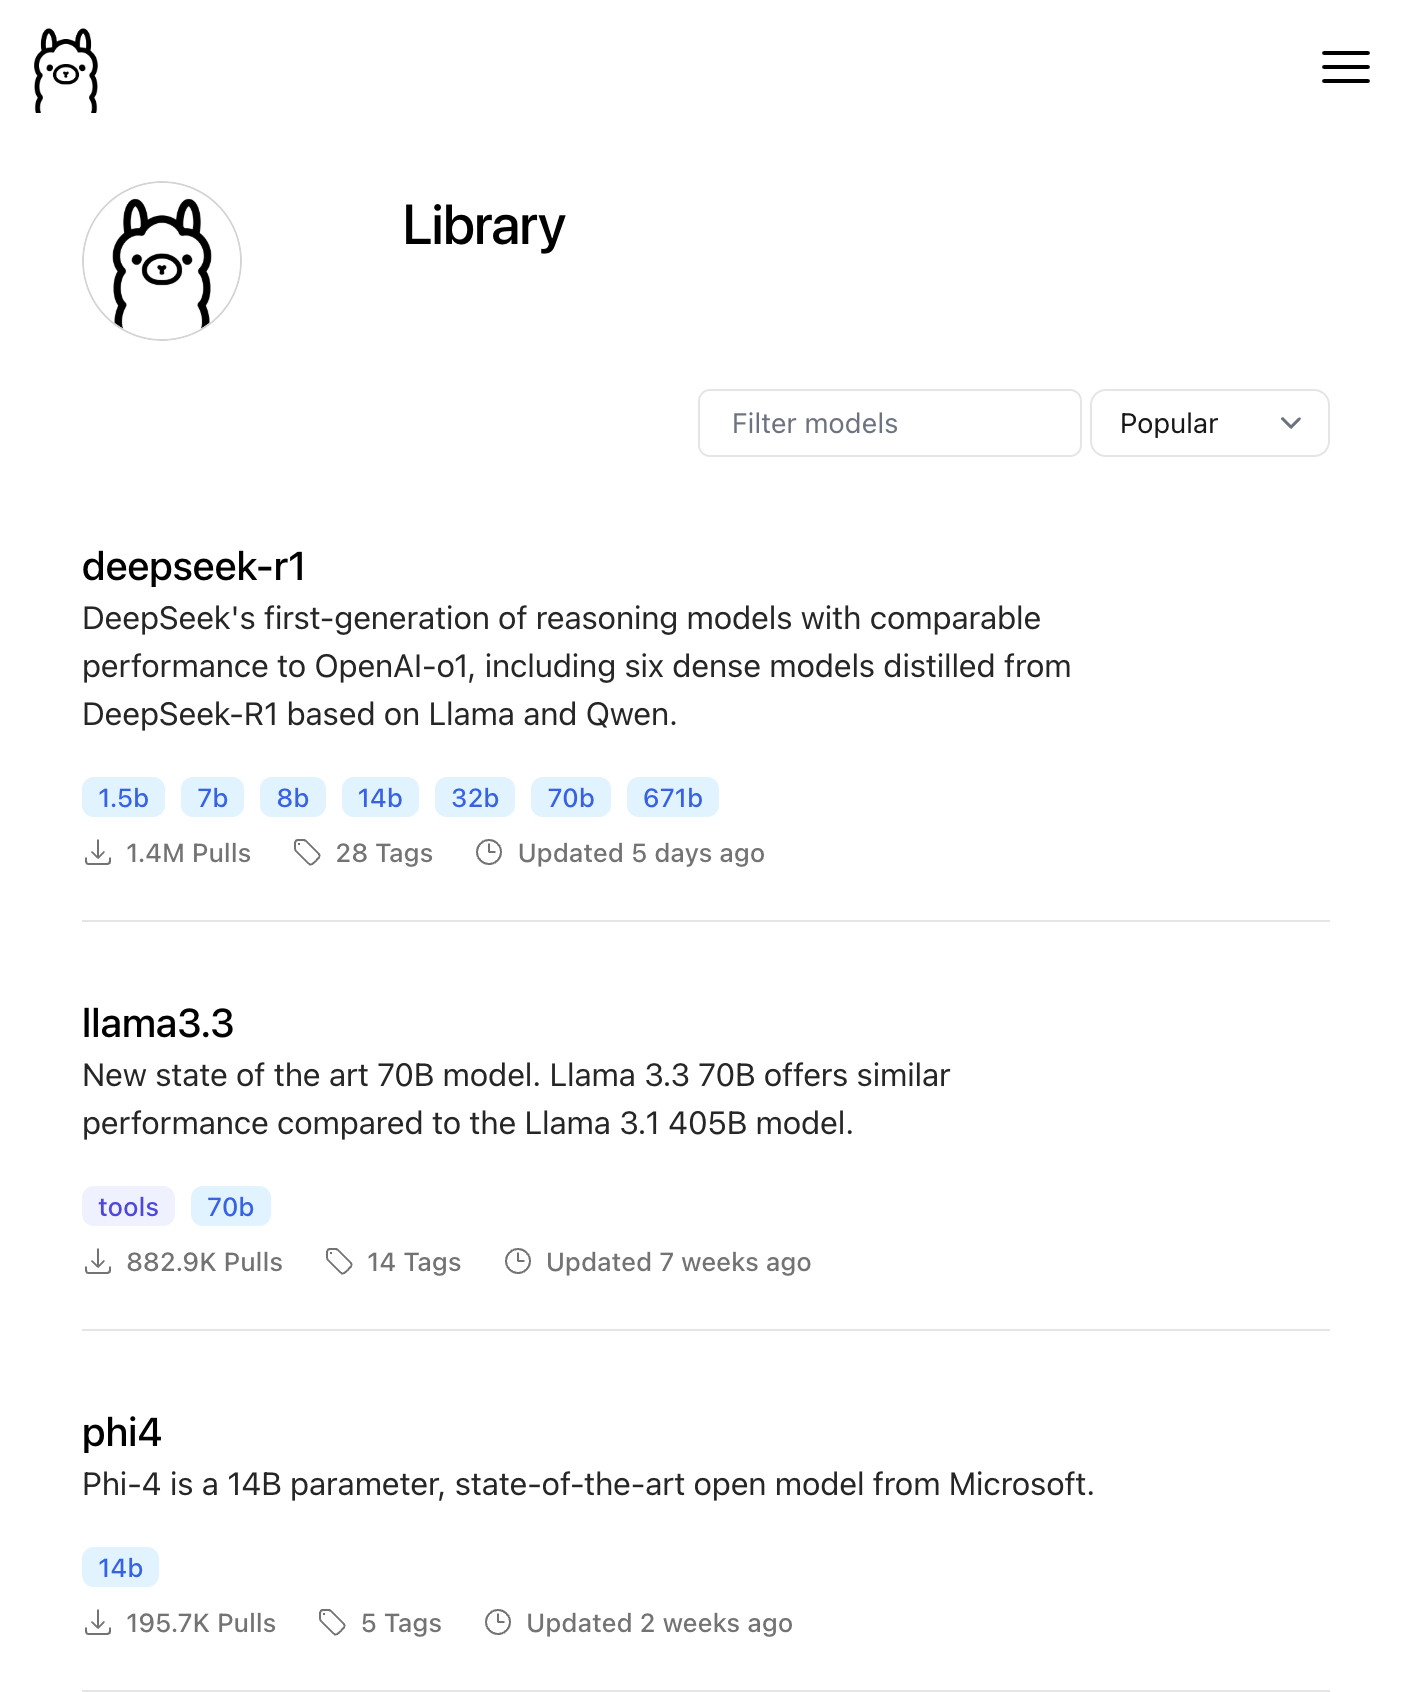
You can easily download models using Ollama’s built-in model registry. Check the available models on the Ollama library webpage.
Here’s how you get the models using the ollama CLI:
-
Open your terminal or command prompt.
-
Use the ollama pull command followed by the model name you want to download.
For example, to download the llama2 model, you would run:
This will download and store the model in your local Ollama model directory.
-
You may specify a model variant. Some models have different variants with varying sizes and capabilities. You can specify the variant you want by appending it to the model name with a colon.
This will pull the 7 billion parameter variant of the llama2 model.
Where are the models stored?
By default, Ollama stores models in the following directories:
- Linux:
~/.ollama/models
- macOS:
~/Library/Application Support/ollama/models
- Windows:
%APPDATA%\ollama\models
You can change the default model directory by setting the OLLAMA_MODELS environment variable.
Please notice that the download time will vary depending on the size of the model and your internet speed.
Once a model is downloaded, you can use it offline.
You can list your locally available models using: ollama list.
To delete a model, use: ollama rm <model_name>.
Following these steps, you can easily download and manage large language models within Ollama and use them for various tasks.
Running models
This command will download and run the llama3.2 model:
pulling manifest
pulling dde5aa3fc5ff... 100% ▕████████████████▏ 2.0 GB
pulling 966de95ca8a6... 100% ▕████████████████▏ 1.4 KB
pulling fcc5a6bec9da... 100% ▕████████████████▏ 7.7 KB
pulling a70ff7e570d9... 100% ▕████████████████▏ 6.0 KB
pulling 56bb8bd477a5... 100% ▕████████████████▏   96 B
pulling 34bb5ab01051... 100% ▕████████████████▏  561 B
verifying sha256 digest
writing manifest
success
>>> Send a message (/? for help)
We can see the available commands in the Terminal:
>>> /?
Available Commands:
  /set            Set session variables
  /show           Show model information
  /load <model>   Load a session or model
  /save <model>   Save your current session
  /clear          Clear session context
  /bye            Exit
  /?, /help       Help for a command
  /? shortcuts    Help for keyboard shortcuts

Use """ to begin a multi-line message.
Fixing “Error: could not connect to ollama app, is it running?”
If ollama run or a Python call returns Error: could not connect to ollama app, is it running?, the background Ollama server is not started. On Linux, or when Ollama was installed via Homebrew, start it in a separate terminal:
Then re-run your ollama run <model> command. On the macOS and Windows desktop apps, launching the Ollama application starts the server automatically.
Model parameters
When operating a model, it may be necessary to adjust its parameters to enhance performance.
Ollama offers several parameters that allow you to fine-tune the behaviour of large language models (LLMs) during text generation. These parameters can be specified in a Modelfile or passed as options when using the ollama run command or the Ollama API.
These parameters are found in the GitHub repository Ollama Model File.
Here are some of the key Ollama parameters:
num_predict: sets the maximum number of tokens to predict when generating text. The default value is -1 for infinite generation. num_predict 100` (limits output to 100 tokens)num_ctx: sets the size of the context window, which determines how many tokens the LLM can use as context for generating the next token.
Larger values allow the model to “remember” more of the conversation
history. PARAMETER num_ctx 4096 (sets context window to 4096 tokens)temperature: controls the “creativity” of the model. Higher values
make the output more random and creative, while lower values make it more
focused and deterministic. PARAMETER temperature 0.7 (sets the temperature
to 0.7)top_k: limits the token selection to the top k most likely
tokens. Helps prevent nonsensical or irrelevant outputs. PARAMETER
top_k 40 (considers only the top 40 most likely tokens)top_p: limits the token selection to a cumulative probability p.
Alternative to top_k can lead to more diverse outputs. PARAMETER top_p
0.9 (selects tokens until cumulative probability reaches 0.9)repeat_penalty: penalises repetition of token sequences, encouraging
novel text generation. PARAMETER repeat_penalty 1.2 (applies penalty
of 1.2 for repeated sequences)stop: specifies stop sequences that, when encountered, cause the LLM
to stop generating text. PARAMETER stop "</s>" (stops generation when
the end-of-sentence token is encountered).mirostat: enables or disables the Mirostat sampling method, aiming to balance coherence and diversity in the generated text. It is not specified, but it can be enabled/disabled through API or command line.mirostat_eta, mirostat_tau: fine-tune Mirostat sampling method behaviour. It is not specified but can be fine-tuned through API or command line.seed: sets random number seed for reproducibility. PARAMETER seed 42 (sets seed to 42).num_gpu, num_thread: control use of GPUs and threads for model execution. It is not specified but can be set through API or command line.
To set these parameters, we can use:
-
Modelfile: Define parameters in a Modelfile to customise default model behaviour.
This Modelfile sets the context window to 8192 tokens, the temperature to 0.8, and the top_k value to 50 for the llama2 model.
 FROM llama2
 PARAMETER num_ctx 8192
 PARAMETER temperature 0.8
 PARAMETER top_k 50
-
Command Line: Pass parameters as options when using ollama run command.
-
API: Include parameters in the request body when using the Ollama API.
What Is DeepSeek R1?
DeepSeek R1 is a large language model developed by the Chinese company DeepSeek. It is designed for tasks requiring reasoning and problem-solving.
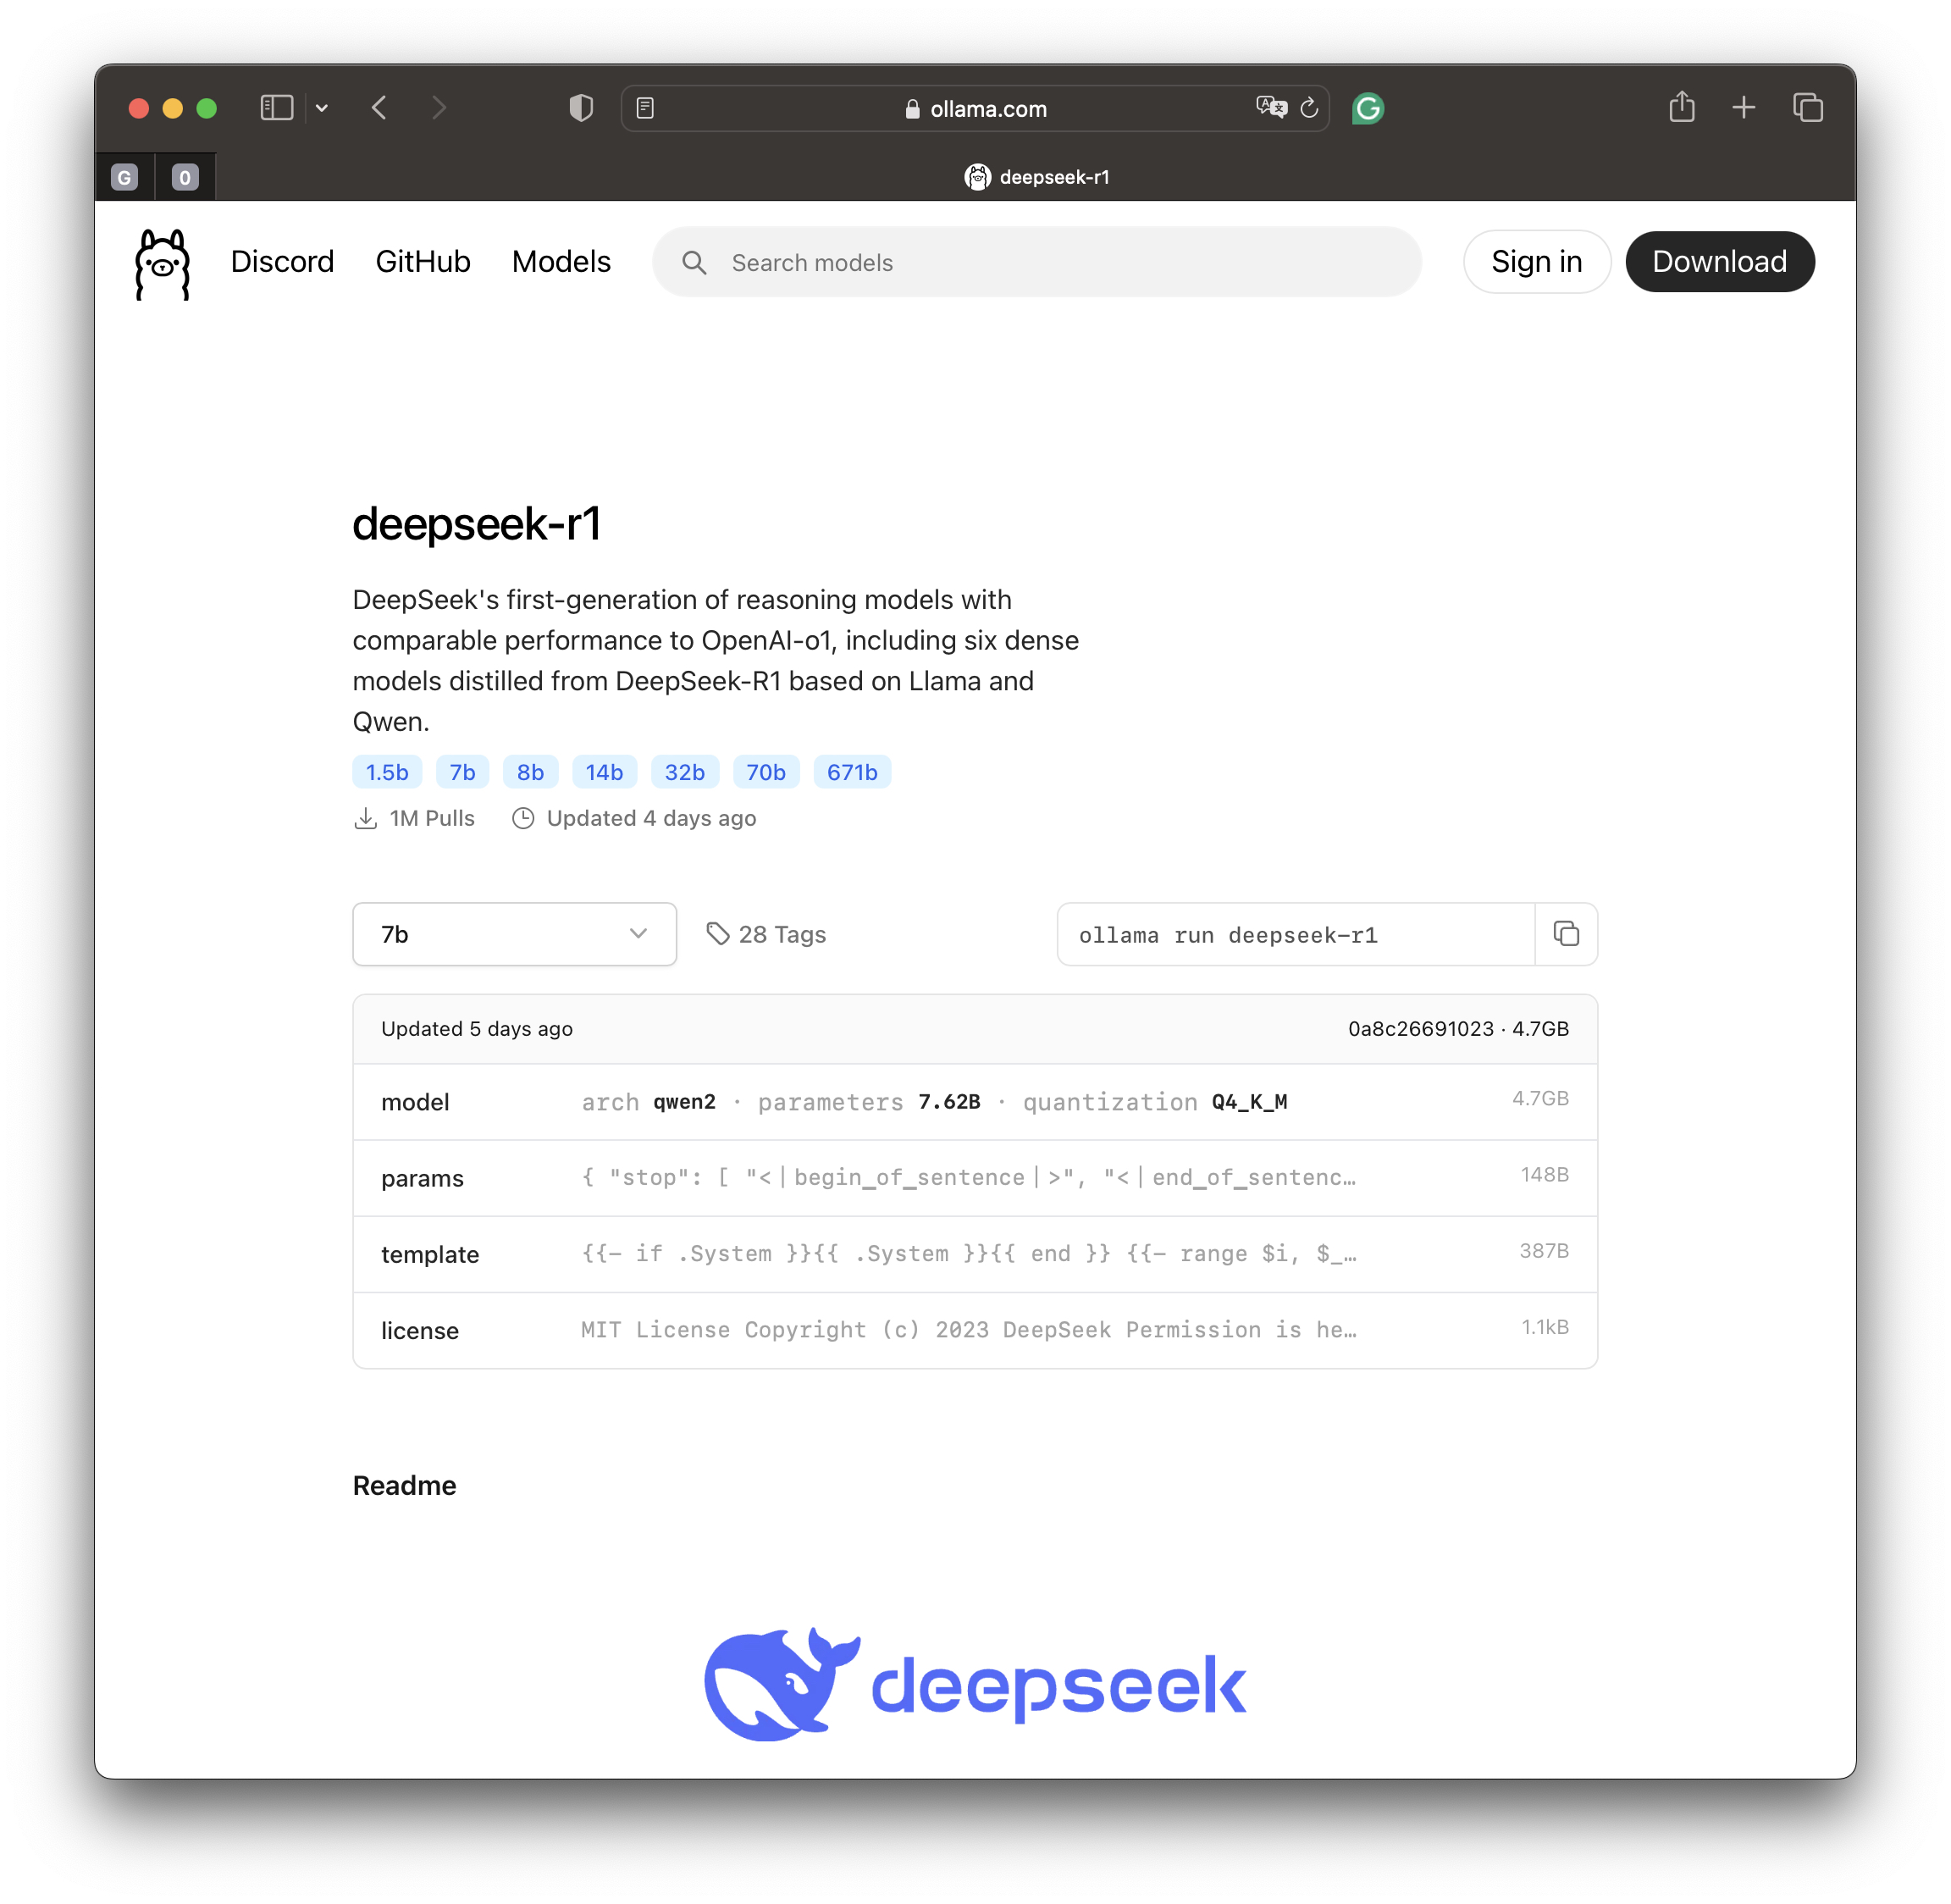
DeepSeek R1 models match OpenAI-o1 performance. They feature six dense models distilled from DeepSeek-R1 based on Llama from Meta and Qwen, which is a LLM built by Alibaba Cloud. There are multiple model sizes, and larger models require more GPU power to run.
DeepSeek R1 is open-source, allowing developers flexibility in customising and avoiding vendor lock-in.
While it shows promise in coding, math, and reasoning, it has a limited track record and potential concerns regarding bias and privacy due to its origin. DeepSeek R1 could be a strong alternative to models like ChatGPT, but staying updated on its development and performance is essential.
Update: DeepSeek hasn’t stood still since R1’s January 2025 debut. R1 itself got a mid-2025 refresh (R1-0528), and DeepSeek’s flagship line has since moved on to the V3 series and, as of April 2026, V4 (with V4-Pro and V4-Flash variants, and V4.1-Flash following in September 2026). If you want DeepSeek’s current strongest model rather than the original R1, look at their changelog. This post’s Ollama steps still work fine for running R1 locally — I just don’t want you thinking R1 is DeepSeek’s latest and greatest anymore.
Downloading DeepSeek R1 with Ollama (ollama pull deepseek-r1)
Running DeepSeek R1 with Ollama starts with finding the model: on the Ollama website, you can search for many models, including DeepSeek, or browse every tag directly on the official DeepSeek R1 model library page.
Update: when this post was first written, the untagged deepseek-r1 name pulled the smallest 1.5b variant by default. That’s no longer true — Ollama has since re-pointed the untagged tag to the DeepSeek-R1-0528-Qwen3-8B checkpoint (a mid-2025 refresh of R1), so a bare ollama pull deepseek-r1 today gets you the 8b model, not 1.5b. If you specifically want the smallest model, tag it explicitly, as we do below — ollama run pulls the model automatically if you don’t have it yet:
ollama run deepseek-r1:1.5b
pulling manifest
pulling aabd4debf0c8... 100% ▕████████████████▏ 1.1 GB
pulling 369ca498f347... 100% ▕████████████████▏  387 B
pulling 6e4c38e1172f... 100% ▕████████████████▏ 1.1 KB
pulling f4d24e9138dd... 100% ▕████████████████▏  148 B
pulling a85fe2a2e58e... 100% ▕████████████████▏  487 B
verifying sha256 digest
writing manifest
success
Prompting DeepSeek R1: CLI, Files, and Python
🔒 Subscribe to keep reading.
Conclusion
🔒 Subscribe to keep reading.
References
🔒 Subscribe to keep reading.